An API integration alert should identify the affected business record, explain what failed in plain language, show whether a retry is pending, and tell the operator what action is safe. That matters most when an operation may have reached its destination even though the response was lost: a careless retry can create a duplicate. Design the notification around recovery decisions, then test it with the people who will handle failures.
An alert should make the next safe action clear
An API integration alert should tell an operator what failed, which business record is affected, whether the system will try again, and what action is safe now. “Integration error” is not enough: it leaves staff guessing whether to wait, correct data, or submit the transaction again.
The goal is not to expose every technical detail in a notification. It is to give the person responsible enough context to find the failure, avoid making it worse, and reach a useful diagnostic trail.
Separate failure types that require different responses
A temporary timeout may mean the receiving system did not answer in time. It does not necessarily mean the receiving system rejected the request; it may even have processed it before the connection failed. An automatic retry could be appropriate, but a manual resubmission could create a duplicate unless the workflow can identify repeated requests.
A validation error is different. For example, a shipment record might be missing a required delivery address. Repeating an unchanged request will not fix it; the source data needs correction. Authentication failures, rate limits, and destination outages also call for different handling. Label the failure category in ordinary language and provide a technical code or trace reference for support staff.
An alert should not claim that an operation failed completely if its outcome is uncertain. Say that delivery is unconfirmed, identify whether a retry is pending, and direct the operator to check the destination before taking a potentially duplicative action.
Include identifiers and timing, not just an error message
An operator needs to locate the right transaction quickly. Include a stable business identifier, such as an order or invoice number, plus the workflow name and the time of the failed attempt. If several records were affected, report the count and provide a secure way to inspect the individual items rather than sending a wall of record data.
Useful status details include the last attempt, attempt count, and next scheduled action. If the system has stopped retrying, say so. If it will retry automatically, give the operator a clear way to see that state. A request ID or correlation ID—a reference that connects related system activity—can help a developer trace logs without exposing sensitive payloads in email or chat.
Keep sensitive personal, payment, or business data out of broad notification channels. Show only what the recipient needs to identify the record, and link the alert to an access-controlled operational view where fuller details are appropriate.
Make recovery instructions specific and bounded
Tell the operator whether to wait, correct source data, ask an administrator to restore access, or escalate the issue. Avoid vague instructions such as “contact support” when the person can safely resolve a missing field themselves. Conversely, do not invite staff to edit a financial or fulfillment record if that change requires review.
Define what an operator must not do. If the integration may have completed the transaction despite a timeout, warn against submitting it again until the destination record has been checked. If a retry is safe because the integration can recognize the same request, explain the approved retry action and its limits.
Some failures need a controlled queue, not repeated notifications. Group repeated alerts for the same issue where practical, while preserving visibility of new affected records. Set ownership by role or monitored queue, and specify who takes over when an issue remains unresolved.
Design retries and alerts as one recovery process
Retries are automated attempts to repeat a failed request. They suit temporary problems, but repeated attempts should be bounded and spaced out rather than firing continuously. The right policy depends on the receiving system and the operation. A routine status lookup and a request that creates an order do not carry the same risk.
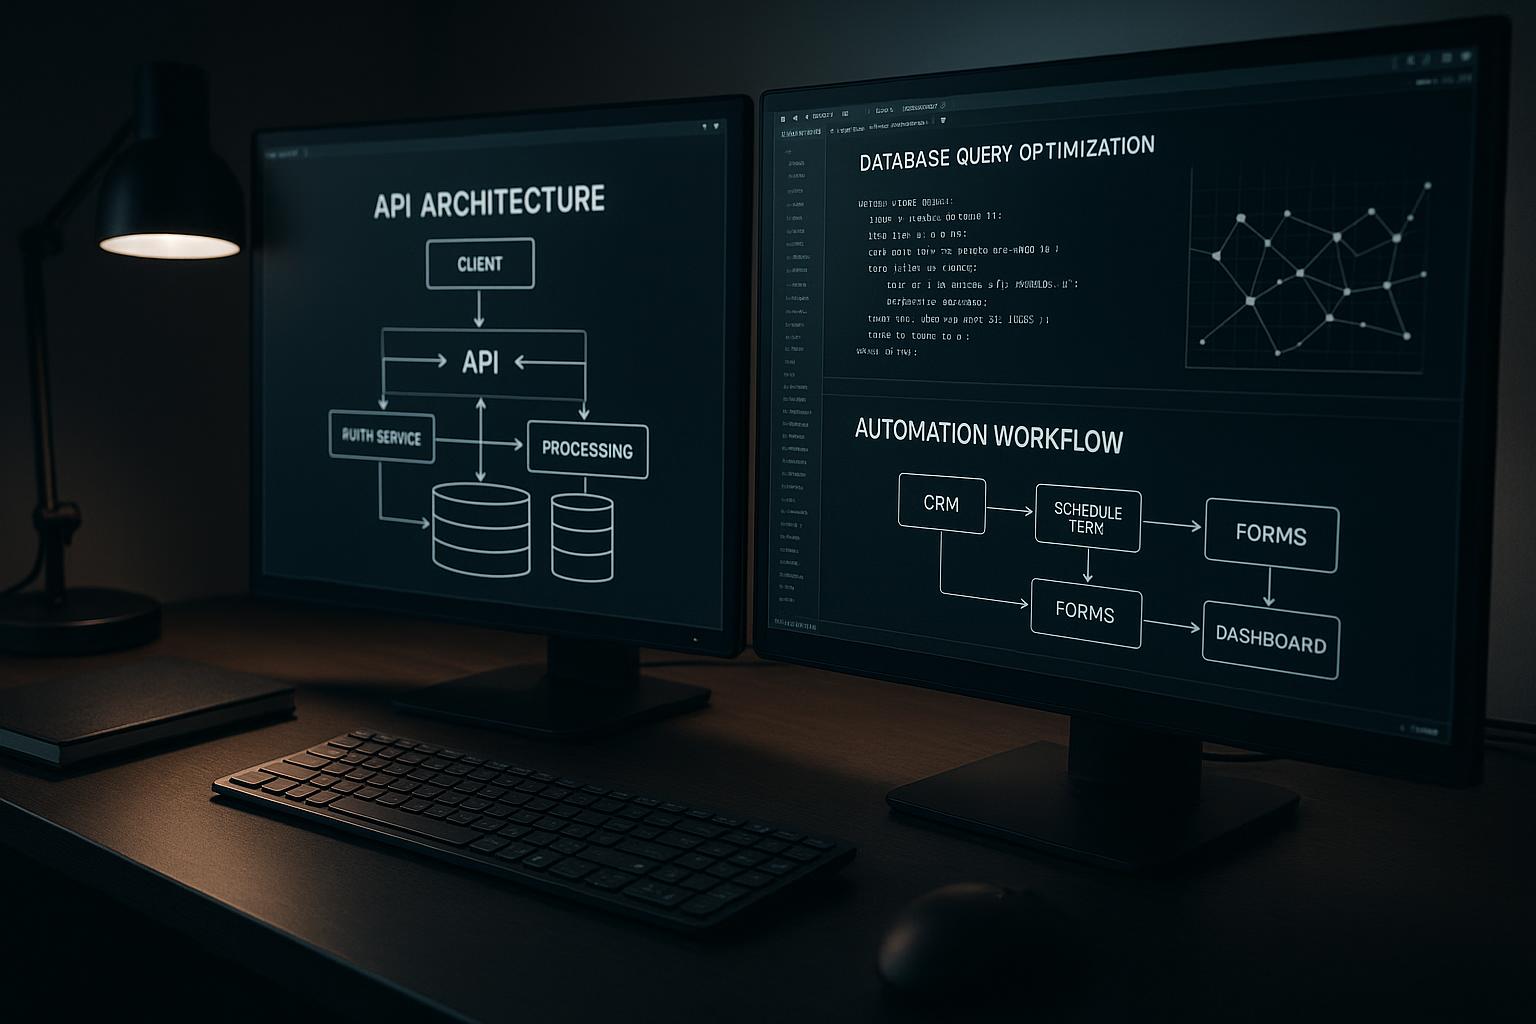
For operations that can be safely repeated, the integration can use an idempotency key: a stable request identifier that lets the receiver recognize a duplicate attempt as the same intended action. Where that protection is unavailable, the workflow may need to verify the destination before retrying or route uncertain outcomes for human review.
The alert should reflect the actual retry policy, not an assumption. If retries stop after a set policy is exhausted, say the workflow is paused and explain how an authorized person can resume it. If a record is held for correction, make clear that fixing the source alone may not automatically restart processing.
Test whether the alert helps someone recover
Before launch, walk through realistic failures with the people who will receive alerts. Test a destination outage, rejected data, expired credentials, a rate limit, and a timeout where the destination’s outcome is uncertain. For each case, verify the notification text, routing, retry status, record access, and the steps needed to resume work.
A useful test asks an operator to explain what happened, which record is affected, whether it is safe to retry, and who owns the next step—without asking a developer to interpret the alert. Also check that alerts do not leak restricted information and that a recovery action leaves a trace of who did what.
This level of alerting may be unnecessary for a low-impact integration that can be safely retried and checked in a routine report. It becomes important when failures can delay fulfillment, lose financial records, or leave staff uncertain about whether a transaction occurred. The practical next step is to map one critical workflow from source event to confirmed destination record, then draft an alert for each meaningful failure state.
Before you configure the alert
- Name the workflow and the affected business record, such as an order number or invoice ID.
- State the failure in plain language and distinguish a temporary delivery problem from a rejected or invalid record.
- Show when the problem occurred, how many attempts have been made, and whether another retry is scheduled.
- Tell the operator what action is safe, what must not be repeated, and where to review the source and destination records.
- Route the alert to a named role or monitored queue, and include an escalation path for unresolved failures.
- Test alerts using realistic failures, including expired credentials, invalid data, rate limits, and an unavailable destination.
Questions about this approach
Should every failed API request send an immediate alert?
Not necessarily. Send urgent alerts for failures that block important work, create uncertain outcomes, or need prompt human action. Routine transient errors can often be retried automatically and summarized in a monitored report, provided unresolved failures still have an owner and a clear route to investigation.
What technical details should an alert include?
Include a stable business identifier, workflow name, failure category, timestamp, retry state, and a trace reference when available. Keep sensitive payloads out of broad channels; provide fuller details only through an access-controlled view.
Can an operator simply retry the failed request?
Only when the workflow can safely recognize the same intended operation or you have confirmed the destination did not process it. If the outcome is uncertain, instruct the operator to check the destination record or follow a controlled review process before resubmitting.
For help applying this approach, explore our API integration and custom programming services.
Discuss your project with Full Blown Studio
Tell us what needs to work better and what you have tried. Discuss your project, email bob@fullblown.com, or call (661) 429-0940.